Two Ways to Resume an AI Agent From a Checkpoint
More infrastructure is showing up for long-running agents, and it is converging on one requirement: the run has to survive the machine.
In April, LangChain described it plainly.
"When a worker crashes, the run's lease is released and another worker picks it up from the latest checkpoint."
Simple sentence. There are two ways to build it, and they fail very differently.
Two designs
Keep the state on the machine. The agent's files sit on local disk and its working state sits in RAM. When your orchestrator calls pause, the platform copies both out to a snapshot. Creating one of these is close to instant: around 80ms on E2B, with no cold starts.
Never put the state on the machine. The workspace is a networked volume that was never part of the compute. There is no copy step because there is nothing to copy.
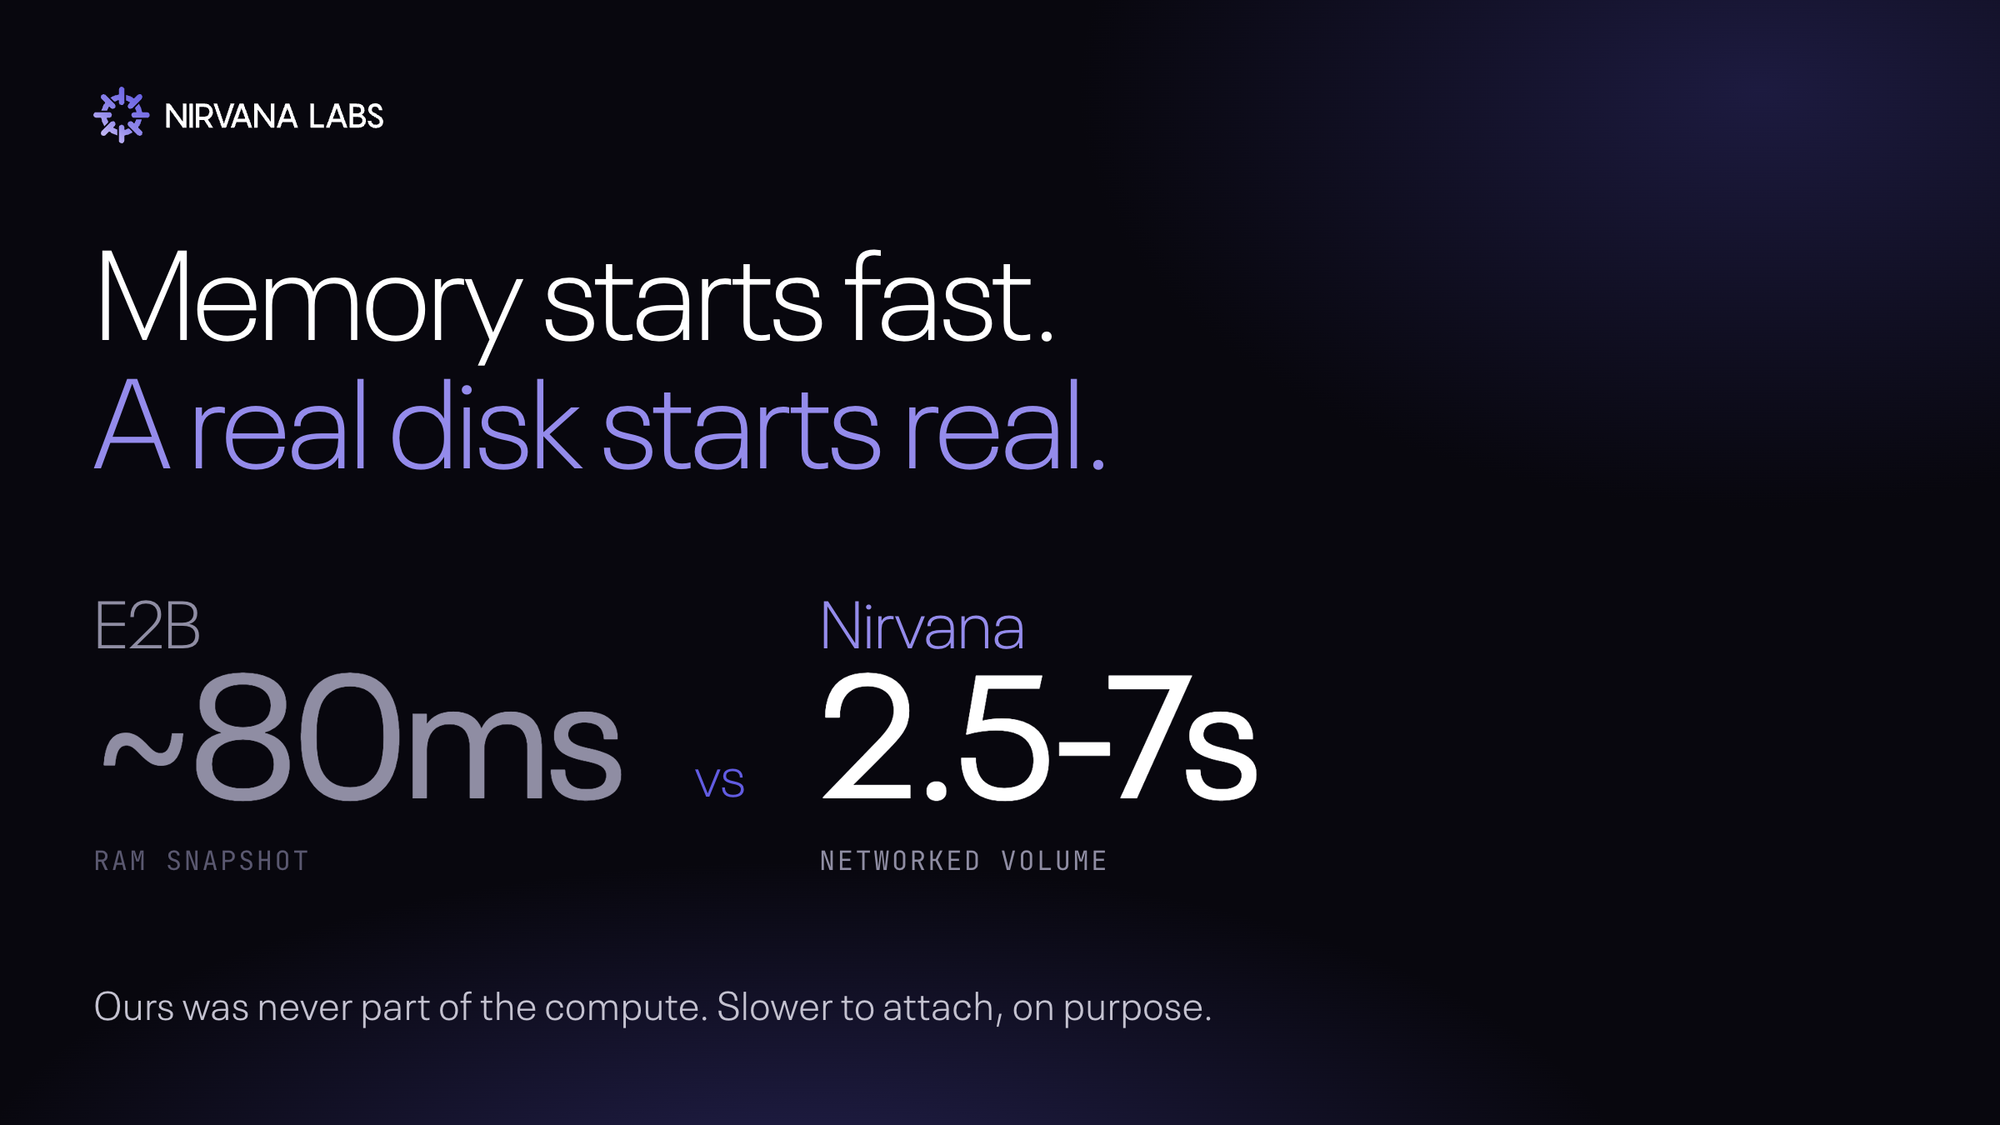
That second one is ours, and it starts slower. Roughly 2.5 seconds, or 6 to 7 on a persistent first boot. A real disk attaching to a real machine takes real time, and we are not going to pretend otherwise.
Once it is running, the trade inverts
Same architectural choice, opposite result.
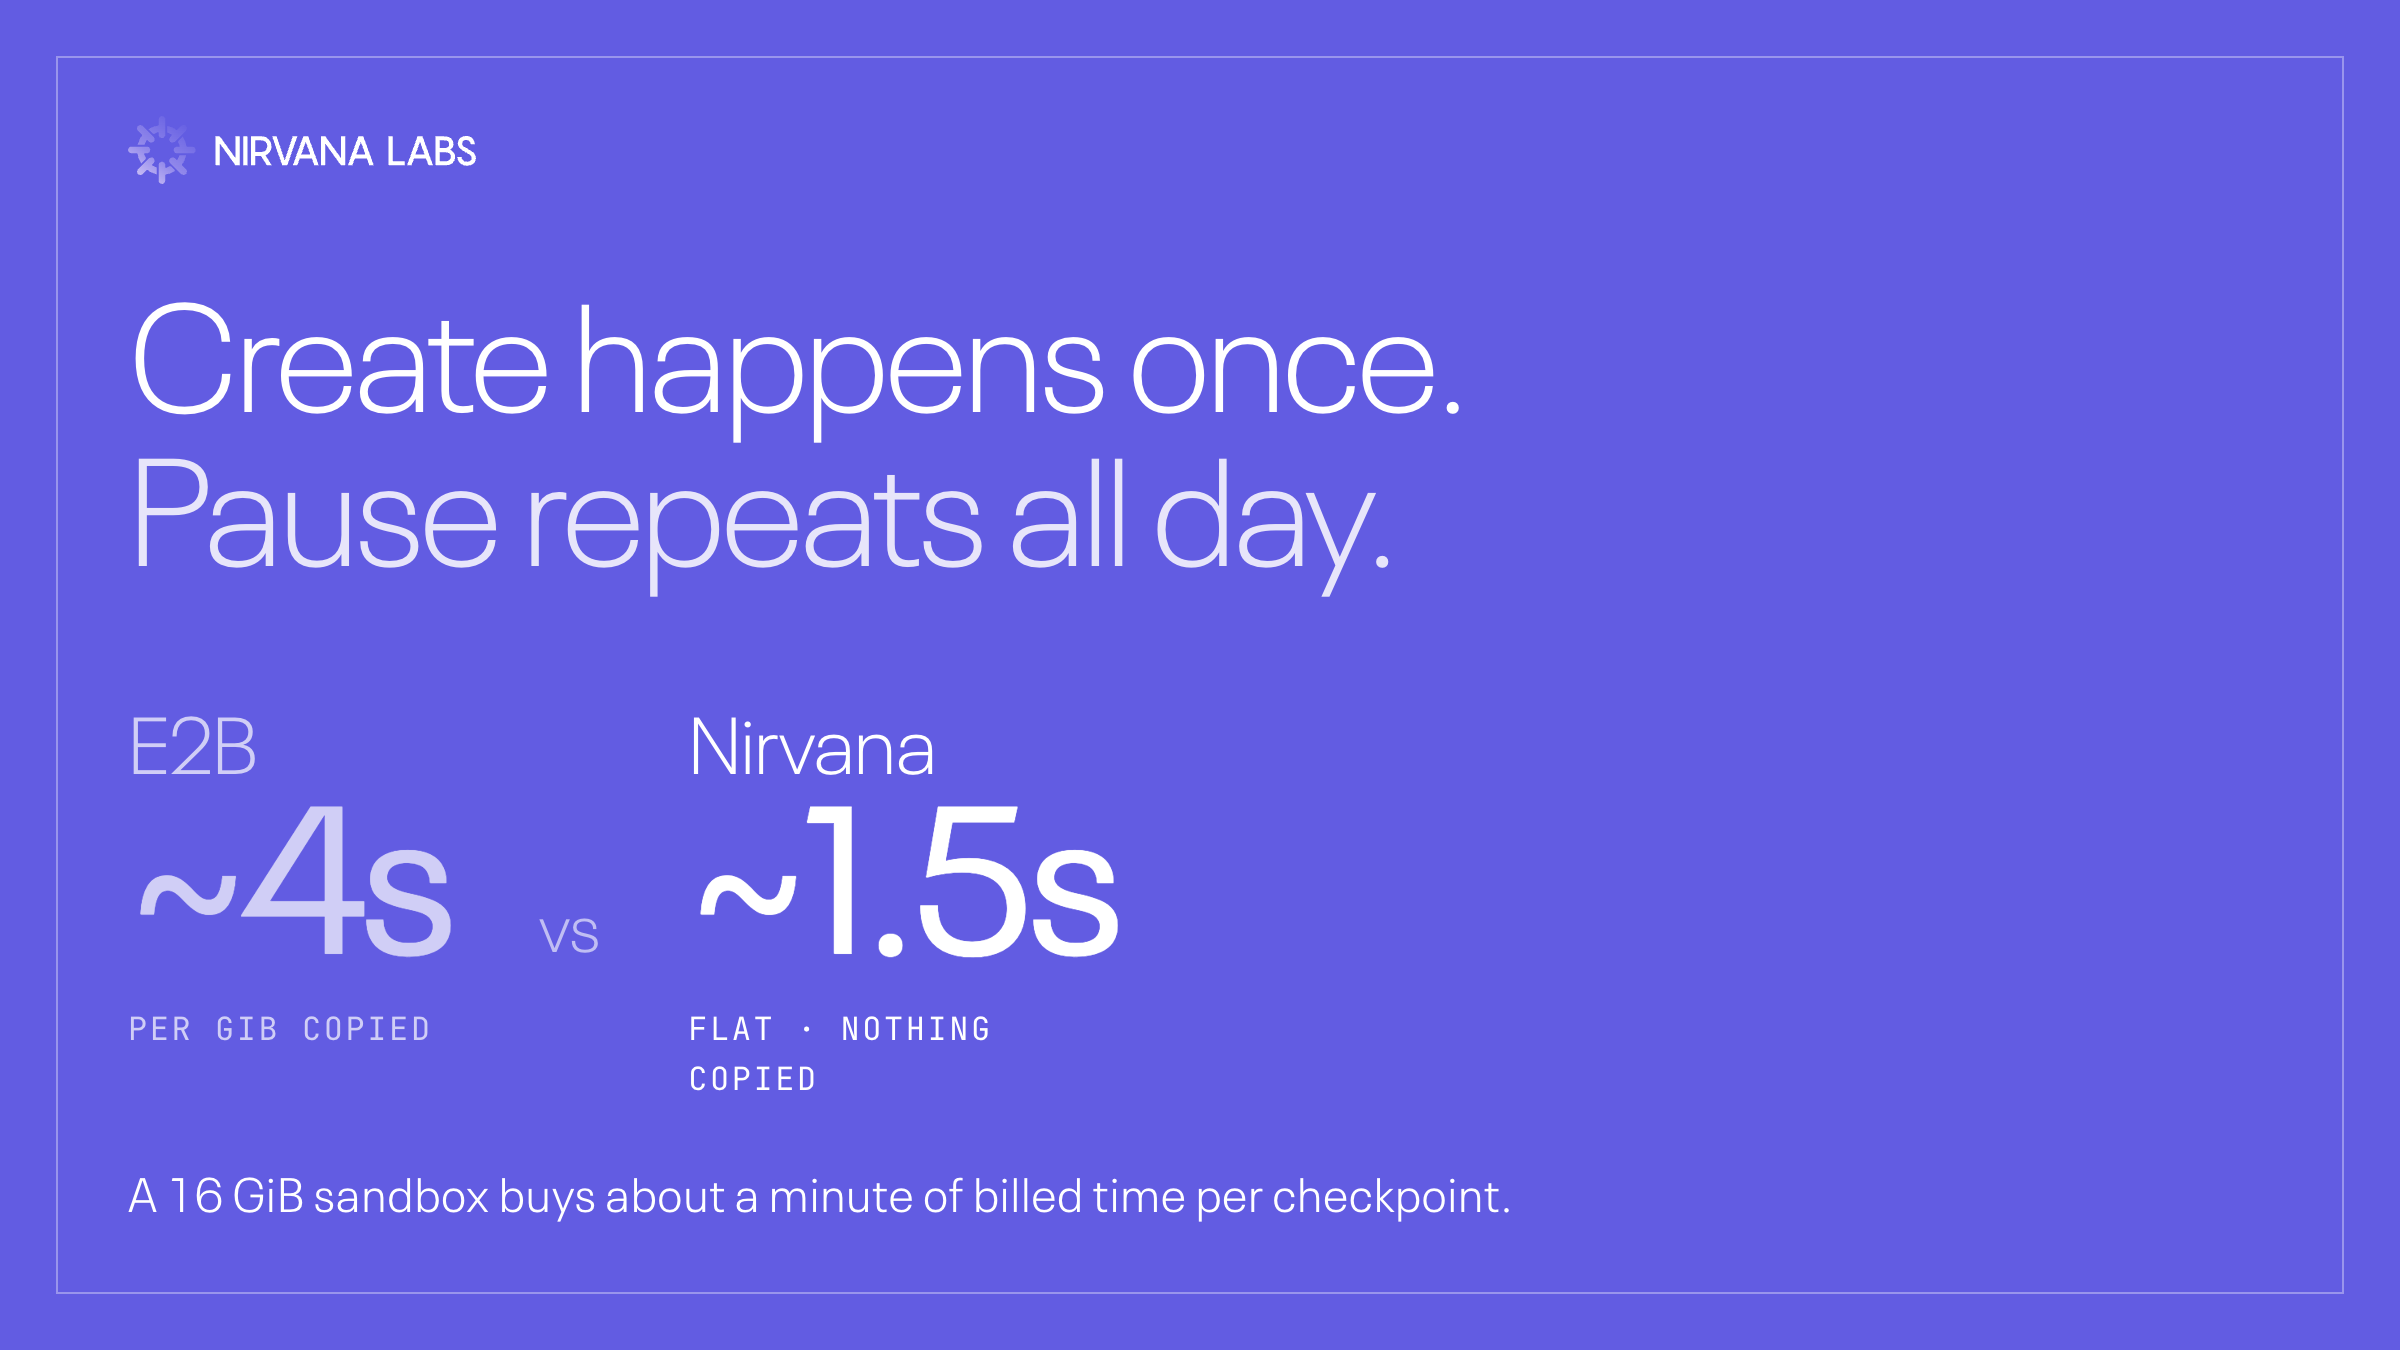
Copying memory means pause scales with memory: about 4 seconds per GiB. A 16 GiB sandbox spends roughly a minute of billed time entering every checkpoint. Checkpoint more often to lose less work, and you pay more to checkpoint.
Ours is about 1.5 seconds, flat, at any size, because nothing is being copied.
| Copy-out design | Networked volume | |
|---|---|---|
| Create | ~80ms | ~2.5s, 6-7s first boot |
| Pause | ~4s per GiB | ~1.5s flat |
Create happens once per sandbox. Pause and resume happen thousands of times a day across a fleet. Nearly every comparison in this category measures the first one.
And machines die
Spot reclamation. Node upgrades. Autoscaler consolidation. OOM kills. None of these call pause first, and pause is the only save point in the copy-out design.
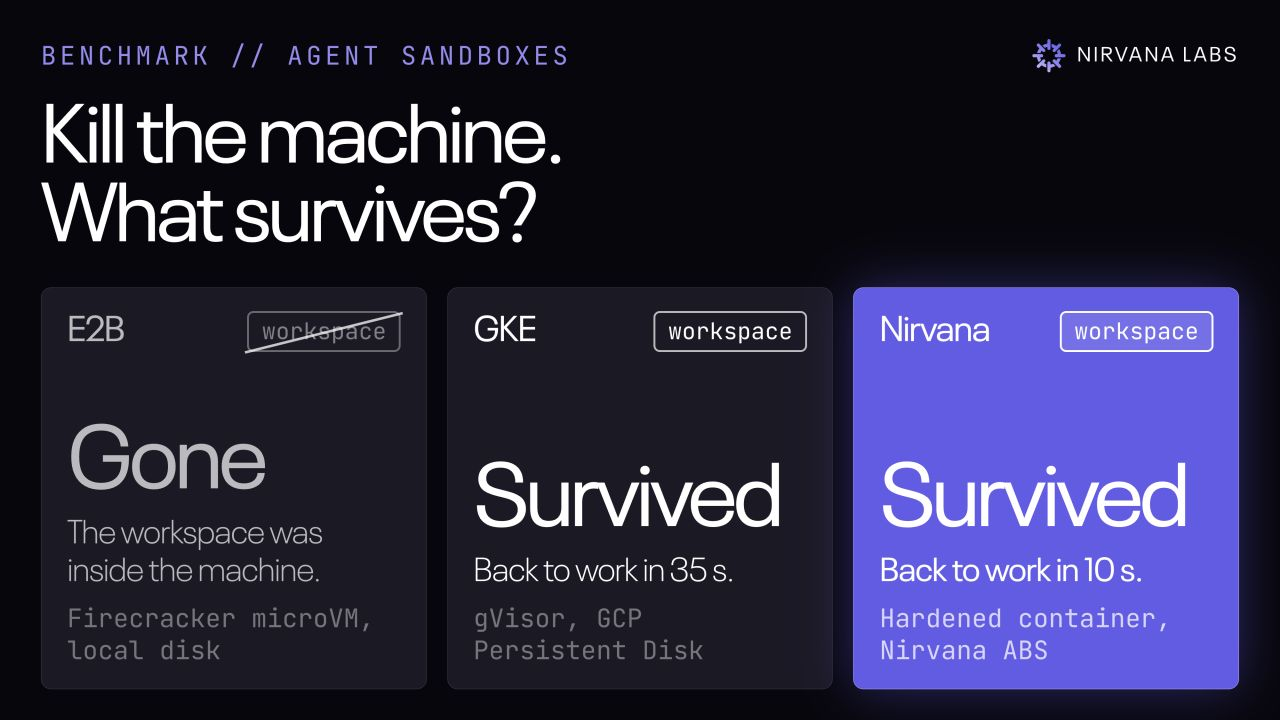
Quirq benchmarked that case across Nirvana, Google Kubernetes Engine and E2B, compute matched at 8 vCPU. Process killed mid-write, pod rebuilt under a new UID:
- Nirvana recovered 5,501 of 5,501 checkpoints
- E2B recovered 0 of 5,000
- Commit p99: 12.4 ms against 72.0 ms on GKE
- Durable checkpoints per second: 18,733 against 3,148
E2B recovering none is not a bug. It is the copy-out design behaving exactly as designed, in the case where nothing called pause.
The work gets paid for twice
LangChain's own framing: an agent that dies twenty minutes in cannot afford to restart, because "the agent already paid for the tokens and executed the tool calls."
That is the first payment, already spent. The second is the sandbox time to do the work again. A kill at hour seven redoes seven hours, and if interruptions arrive more often than the job takes, it never finishes at all.
Long running agents need persistent sandboxes
Agents are going to do more. Longer runs, more tool calls, more jobs that take hours and cost real money to repeat. Work like that belongs on a genuinely persistent sandbox, where checkpoints are recovered during a crash.
Machines die. Agents die. Your checkpoints and work shouldn't.
About Nirvana Labs
Nirvana Labs is a high-performance storage cloud purpose built for blockchain, AI and databases i.e. the most demanding, real-time, stateful workloads. Accelerated Block Storage (ABS) offers 20K baseline IOPS included, no over provisioning. Nirvana Kubernetes Service (NKS) with Karpenter auto-scaling, high clock-speed compute and private networking. Backed by Jump Trading, Crucible, etc with 50+ customers live in production today.
Learn more at Nirvana Labs
Nirvana Cloud | Pricing | Blog | Docs | Changelog | LinkedIn | Twitter | Telegram | YouTube
Related Posts
What Is a Harness? The Agent, The Model, the Harness, and the Sandbox
An agent harness turns a model's decisions into action: it runs the loop, executes each tool call, keeps the notes and calls time. The word is new, the thing is not. What changed in 2026 is that OpenAI, Vercel and LangChain started selling it.
GPU Starvation Is a Data-Path Problem, Not Just a Chip Problem
Nirvana's layer is high-performance block storage. ABS ships 20,000 baseline IOPS against AWS gp3's 3,000 default, bursting to 600,000, and in our own benchmarks runs 10.5x faster than gp3 on cold-read analytical queries.
CPUs are back: Why agentic AI needs more CPUs than GPUs, and what's next for cloud
CPUs are back: Why agentic AI needs more CPUs than GPUs, and what's next for cloud
Powering AI, blockchain, and
databases
