A long-running AI agent is one that works for hours or days across many steps, holding state the whole time: a filesystem, a checkpoint history, installed packages. The cloud question that raises is not how fast a sandbox starts. It is how long a single session may last, and what survives when the machine running it dies.
TL;DR
- No single best cloud. Four constraints decide it: session length, crash durability, isolation, and how much orchestration you want managed.
- Session caps run from Modal's 5-minute default to Northflank and Nirvana running until you stop them.
- Create speed happens once. Pause, resume and recovery repeat thousands of times, and nobody benchmarks those.
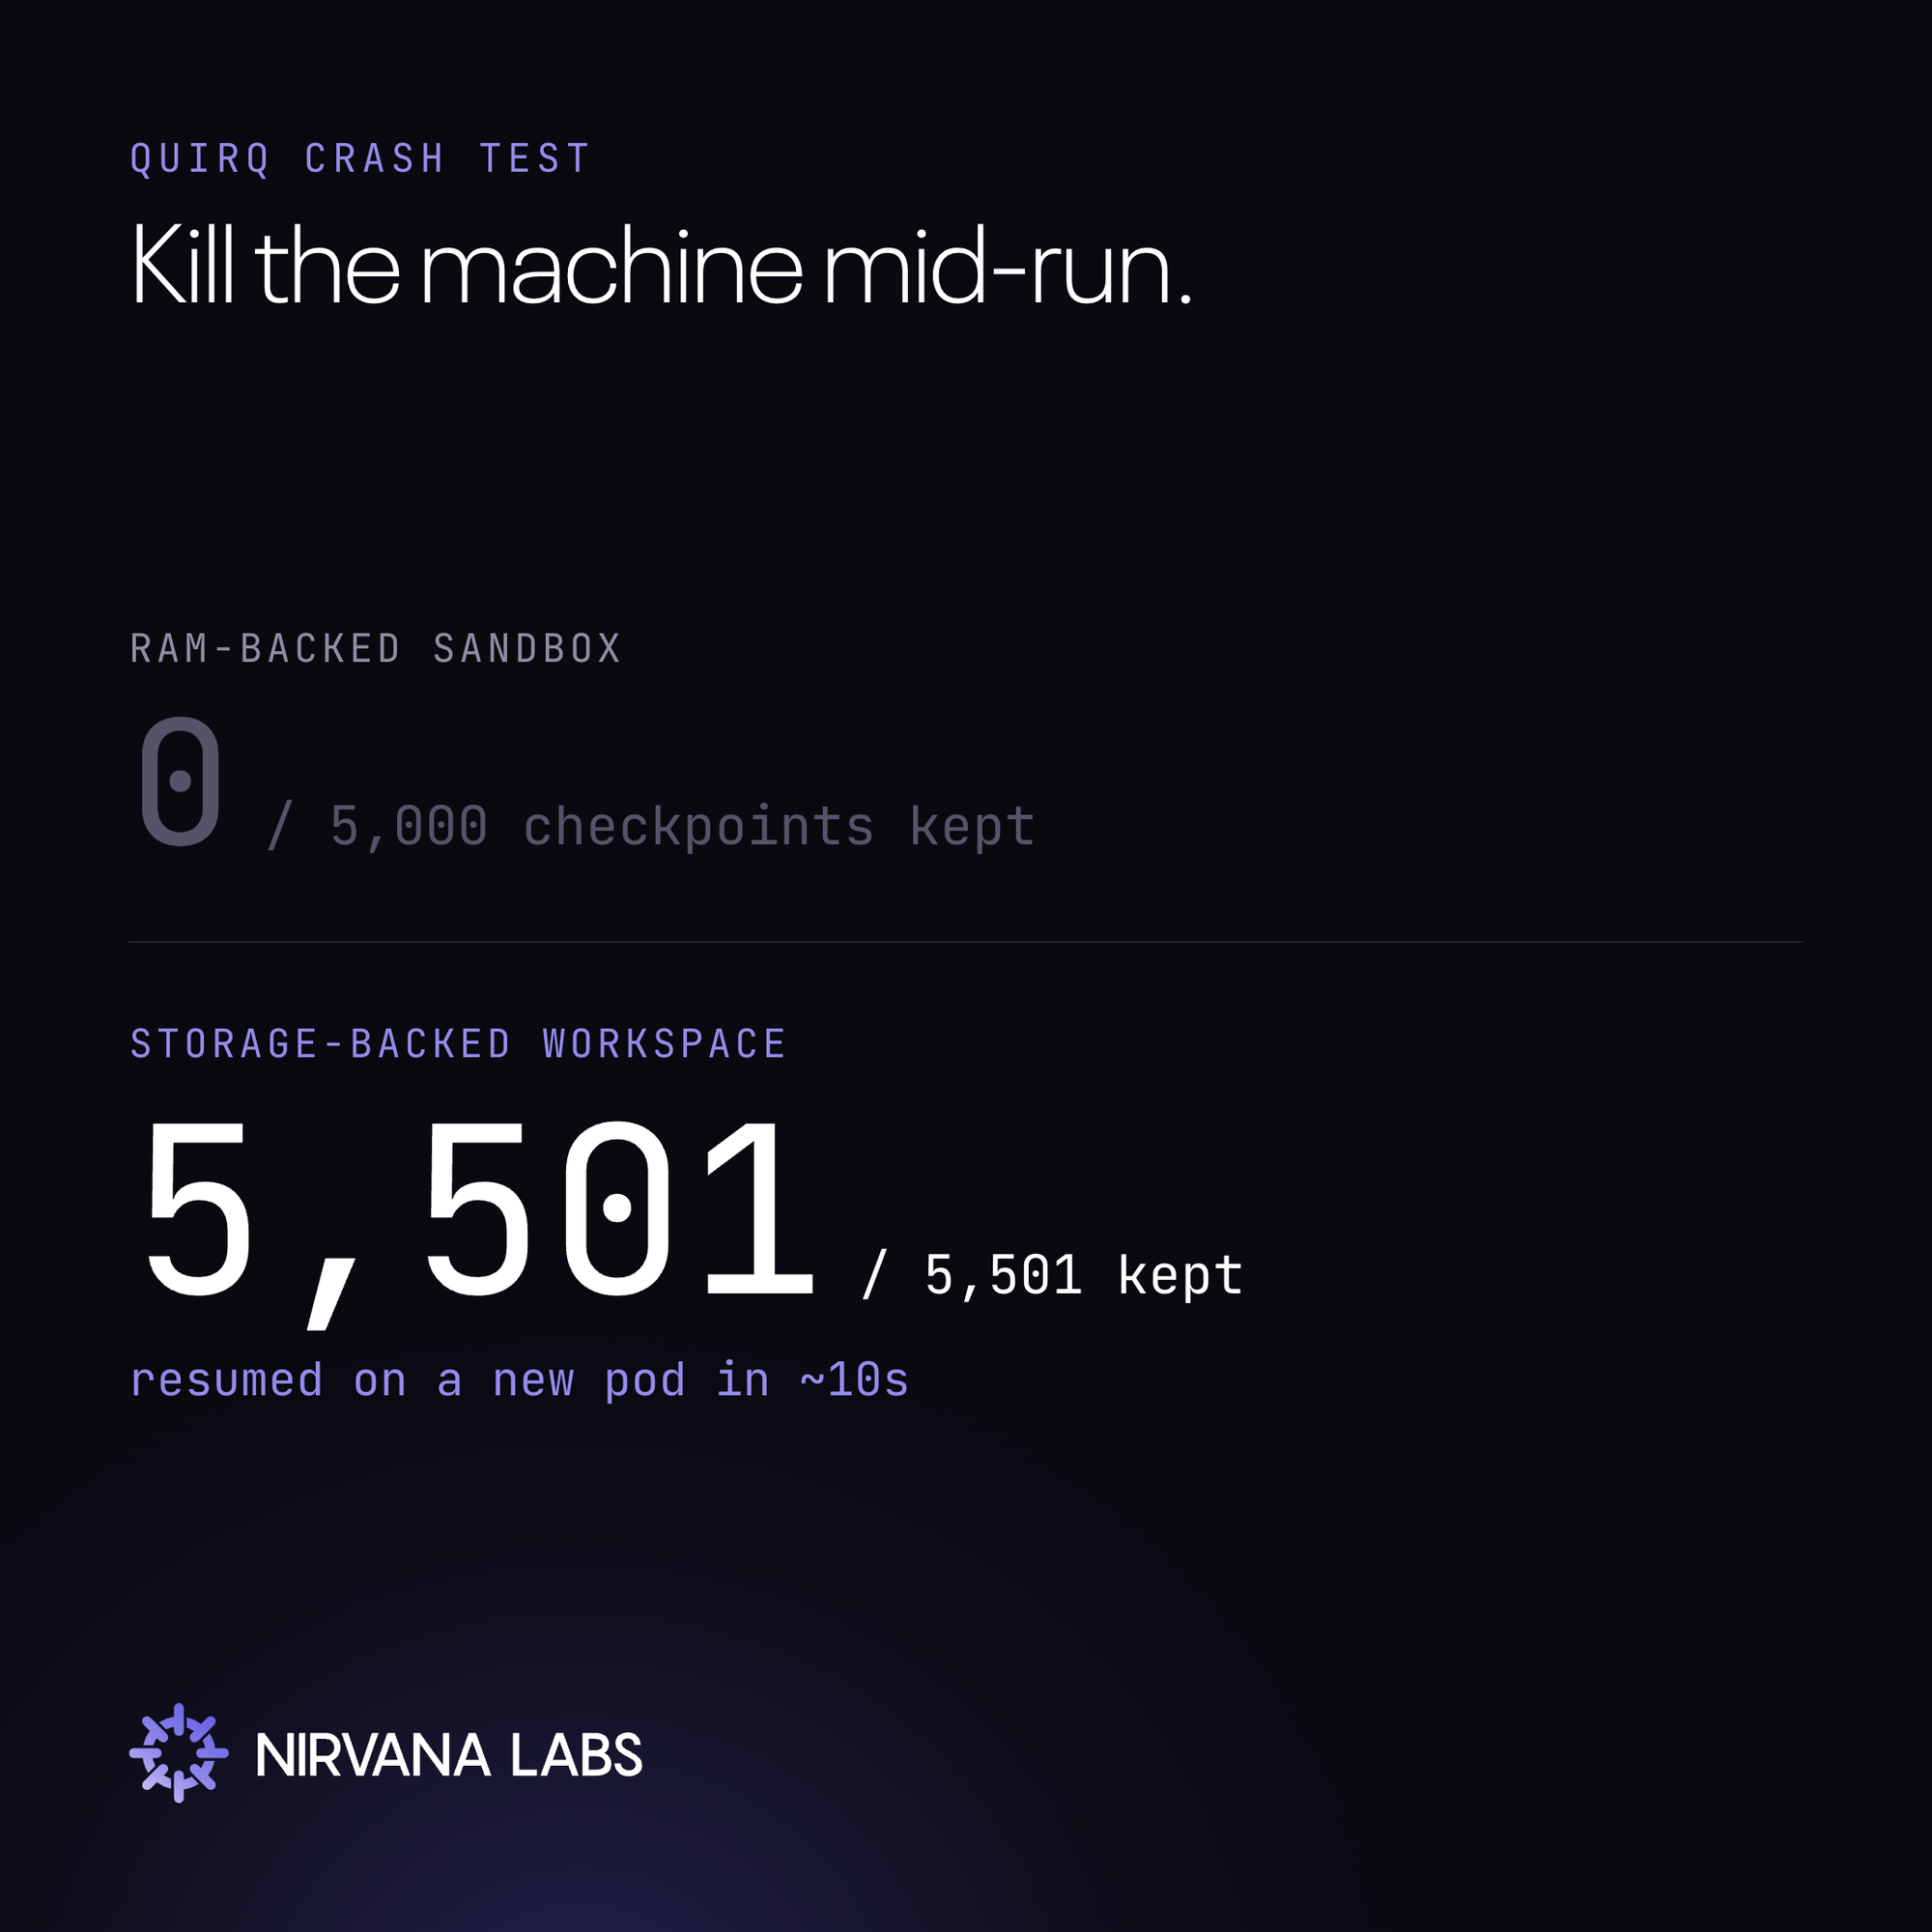
- Killed mid-job, a RAM-backed sandbox lost all 5,000 checkpoints; a storage-backed workspace kept 5,501 of 5,501 and resumed in ~10s.
- Compliance beats performance: if data cannot leave its cloud boundary, the rest does not apply.
What is a long-running AI agent?
Most agent demos finish in seconds: one prompt, one tool call, one answer, nothing to keep.
A long-running agent differs in kind, not just duration. It refactors a codebase over six hours, monitors an API for a week, or runs research across hundreds of steps, accumulating state as it goes: files written, dependencies installed, checkpoints recorded. Stop it halfway and you have not paused a conversation, you have abandoned a workspace.
That state is the engineering problem. A chat agent that crashes retries a request. A long-running agent that crashes loses work that cost real money in model and tool calls.
Do long-running agents break on general-purpose clouds?
Yes, in two unrelated ways.
The timeout ceiling. Standard serverless cuts execution off after minutes, so an agent compiling code for six hours gets killed mid-run. Well understood, and every platform below answers it.
The quiet one. Most sandbox platforms hold the agent's working state in RAM and local disk. It becomes durable only when something copies it out, usually when your orchestrator calls pause. Between two copies, hours of work sit in one place: a machine that can vanish to spot reclamation, a node upgrade, an autoscaler consolidation or an idle timeout.
Machines dying is not an edge case in cloud infrastructure. It is the operating model. Create speed is the number everyone publishes because it benchmarks well, but create happens once. Crashes repeat.
How long can an agent actually run on each platform?
| Platform | Maximum single session | Past the cap |
|---|---|---|
| Modal | 5 min default, to 24 h | Filesystem snapshots, 30-day default, can be set never to expire |
| E2B | 24 h | Pause writes a snapshot, kept indefinitely |
| AWS Bedrock AgentCore | 14 days on Runtime Instances | Managed memory carries context across sessions |
| Vertex AI Agent Engine | No published hard cap | Sessions plus Memory Bank, both GA |
| LangSmith Deployment | Not capped by the platform | Resumes from the last checkpoint |
| Northflank | Until you terminate it | No cap to handle |
| Nirvana Agent Sandboxes | Until you terminate it | Compute releases independently of the workspace |
One correction: the widely repeated "8 hours on AWS" is out of date. AgentCore Runtime Instances raised it to 14 days. Comparisons written before mid-2026 still say eight.
What happens to the work when the machine dies?
Session caps are published. Crash behaviour is not. Three designs:
Snapshot on demand (E2B, Modal). State lives in RAM and local disk; a pause call copies it somewhere durable. E2B restores an agent mid-computation with processes intact, which nothing storage-backed can do. But durability is an event, not a state, and the copy scales with size: E2B's documented pause runs about 4 seconds per GiB of RAM, so a 16 GiB sandbox burns roughly a minute of billed time per checkpoint.
Managed persistence (LangSmith, Bedrock, Vertex). LangGraph checkpoints graph state at each super-step into a backend you configure, asynchronously by default. Good design, but durability is a property of your Postgres, not the framework. Managed agent memory stores conversational facts, not files.
Storage-backed from the write (Northflank, Nirvana). The workspace sits on a volume that was never part of the compute, so nothing needs copying. We measured the gap with Quirq: killing a RAM-backed sandbox mid-run lost all 5,000 checkpoints, while a storage-backed workspace kept 5,501 of 5,501 and resumed on a new pod in about 10 seconds. On GKE with the same disk it took around 35 seconds, because the pod must be rebuilt first.
The honest cost: RAM is not preserved. Our agents restart their process and find their files. E2B's wake up mid-thought.
Which should you choose?
Stop at the first line that describes you.
- Data cannot leave your cloud boundary. Bedrock AgentCore or Vertex. Nothing else here applies.
- You run untrusted or user-generated code. E2B or Modal. Buy the microVM boundary.
- You do not want to own the orchestration loop. LangSmith Deployment, on a persistence backend you have load-tested.
- You want one platform for the agent and everything around it. Northflank: no session cap, volumes to 64 TB, GPUs, BYOC.
- The agent writes heavily for hours and idle cost hurts. Nirvana, with your own orchestration on top. Idle compute releases in 1.46s and resumes in 8.9, about a 10 second round trip whatever the workspace size, so short gaps become worth reclaiming.
Higher lines win: compliance is rarely negotiable, performance usually is.
Still choosing on create time? Run one test: start a real job, kill it at 45 minutes, measure how much work you redo. That number decides more deployments than the pricing page.
FAQ
Is create speed the right thing to compare? Only if your sandboxes are short-lived. Create happens once. Pause, resume and recovery repeat thousands of times across a long-running fleet, and are rarely benchmarked publicly.
How long can an AI agent run on each platform? Modal and E2B cap sessions at 24 hours. AWS Bedrock AgentCore runs to 14 days on Runtime Instances. Northflank and Nirvana run until you terminate them. LangSmith and Vertex publish no hard cap.
What happens to an agent's work if the machine crashes? It depends where state sits. On RAM-backed platforms everything since the last pause is lost. In a Quirq test, a terminated RAM-backed sandbox lost all 5,000 checkpoints; a storage-backed workspace kept 5,501 of 5,501 and resumed in about 10 seconds.
About Nirvana Labs
Nirvana Labs is a high-performance storage cloud purpose built for blockchain, AI and databases i.e. the most demanding, real-time, stateful workloads. Accelerated Block Storage (ABS) offers 20K baseline IOPS included, no over provisioning. Nirvana Kubernetes Service (NKS) with Karpenter auto-scaling, high clock-speed compute and private networking. Backed by Jump Trading, Crucible, etc with 50+ customers live in production today.
Learn more at Nirvana Labs
Nirvana Cloud | Pricing | Blog | Docs | Changelog | LinkedIn | Twitter | Telegram | YouTube
Related Posts
What Is a Harness? The Agent, The Model, the Harness, and the Sandbox
An agent harness turns a model's decisions into action: it runs the loop, executes each tool call, keeps the notes and calls time. The word is new, the thing is not. What changed in 2026 is that OpenAI, Vercel and LangChain started selling it.
Long-running agents: from RAM to disk.
LangChain: when a worker crashes, another worker picks it up from the latest checkpoint. There are two ways to build that. One creates in 80ms and loses everything since the last pause. The other starts slower and kept 5,501 of 5,501 checkpoints through an ungraceful kill.
The expensive way to buy IOPS
If your storage bill is mostly meter, you paid the expensive way. Clouds price capacity cheap and meter IOPS on top: 60% of the bill at 20K IOPS, 84% at 80K, 91% on io2. Which workloads hit the meter, what it costs them, and whether yours should move.
Powering AI, blockchain, and
databases
